
- 7th Annual
- November 17-18, 2026
- Austin, TX
MLOps World | GenAI Summit 2026
Two days of case studies, workshops, and expo on taking AI/ML and agentic systems into production – at the Etter-Harbin Alumni photo – full-bleed hero or browse files
Can’t travel? The virtual day on Nov 16 is free.
The event that takes AI/ML & agentic systems from concept to large-scale production
2 Days • 16 Tracks • 75 Sessions • Vibrant Expo
Why attend
Programmed by a 75+ member Steering Committee of working practitioners – case studies, not product pitches.
Build optimal strategies
Learn the workflows and architectures from teams actively scaling ML, GenAl, and agents in production.
Increase project efficiency
Minimize risk, delays, and missteps with case studies that set the standard for impact and quality.
Make better decisions
Faster calls, backed by hard won lessons from teams shaping agentic systems at scale.
Tracks & track leads
Track lead: Denys Linkov — Head of ML, Wisedocs
This track is for ML engineers looking to go deeper into hardware and kernel knowledge: the new generation of chips, chip architecture, kernels and inference tricks, and what they unlock in LLMs and other models.
Track lead: Hannes Hapke — Director, Open Source, Dataiku
This track is for ML engineers looking to go deeper into hardware and kernel knowledge: the new generation of chips, chip architecture, kernels and inference tricks, and what they unlock in LLMs and other models.
Track lead: Tony Kipkemboi — Staff Engineer, AI Operations Guild. Prev, Founding DevRel Engineer & Partnerships Lead , CrewAI
Learn the harness patterns that keep agents reliable in production: tool permissions and sandboxes, self-correction loops, state and memory under a cost ceiling, evals that hold at volume, and the agent loop itself, from speakers who built and measured them, including the failure modes that forced a redesign.
Track lead: Tony Kipkemboi — Head of Developer Relations, CrewAI
AI usage continues to grow, yet leaders are struggling to quantify the ROI of their investment. In this track you’ll hear from engineers who have debugged and optimized their costs.
Track lead: Suhas Pai — Co-Founder & CTO, Hudson Labs
There is no settled architecture for deciding what an agent should store, retrieve, revise, and forget. In this track, attendees will leave with a stronger understanding for choosing, implementing, and evaluating memory components in an agent system.
Track lead: Tony Kipkemboi — Head of Developer Relations, CrewAI
Being more productive than you were before coding agents makes it easy to be fooled into thinking you’re already at best practice. This track covers coding agents on complex codebases, secure AI-assisted development, and the code review bottleneck with concrete case studies from speakers who’ve gone beyond the hype.
Track lead: Dave Scharbach — Executive Director, TMLS
This track covers coding agents on complex codebases, secure AI-assisted development, and the code review bottleneck with concrete case studies from speakers who’ve gone beyond the hype.
Track lead: Suhas Pai — Co-Founder & CTO, Hudson Labs
AI systems can increasingly self-evaluate and modify their own prompts, tools, memory, code, data, and workflows. This track will focus on ensuring these feedback loops produce genuine, repeatable improvement rather than benchmark overfitting or unstable changes.
Track lead: Suhas Pai — Co-Founder & CTO, Hudson Labs
In a world where models are released daily, how do we build an effective eval approach, or know when the right time is to swap models? This session is designed to help engineers move more quickly, build better products, and save on costs
2 Days of workshops, Case studies, Discussions & Socials
Learn from leading minds, sharpen your skills, and connect with innovators driving safe and effective AI in the real world.

Free Online Stage
- Virtual Day (Nov 16th)
- In-Person Workshops (Nov 17th-18th)
- Workshops (Nov 19th)
Day 1
- Summit:
- Talks, Panels, & Workshops
- Expo:
- Lightning Talks
- Brain Dates
- Community Square
- Startup Zone
- Vendor Booths
- Opening Party
Day 2
- Keynote
- Summit:
- Talks, Panels, & Workshops
- Expo:
- Lightning Talks
- Brain Dates
- Community Square
- Startup Zone
Why attend: Connect & Grow
Grow industry influence
Equip your team to win
Stay ahead of fast-moving competitors by giving your team the insights, skills, and contacts they need to exceed expectations.
Build career momentum
Make every hour count by using our event app to hyper-focus on the right topics and people who will help shape your future in AI.
2025 Summit: Full-Spectrum AI
All themes, talks, and workshops curated by top AI practitioners to deliver real-world value. Explore sessions
2025 THEME: AI Agents & Agentic Workforces
AI Agents for Developer Productivity
This track highlights practical uses of agents to streamline dev workflows—from debugging and code generation to test automation and CI/CD integration.
AI Agents for Model Validation and Deployments
Agents can now assist in model testing, monitoring, and rollback decisions. The track focuses on how teams are using autonomous systems to harden their ML deployment workflows.
Augmenting Agentic Workforces
This track explores how teams are combining human oversight with semi-autonomous agents to scale support, operations, and decision-making across the business.
Agents in Production
Latest Trends in MLOps


2025 THEME: MLOps & Organizational Scale
Governance, Auditability & Model Risk Management
This track covers how teams manage AI risk in production—through model governance, audit trails, compliance workflows, and strategies for monitoring model behavior over time.
MLOps for Smaller Teams
Not every team has a platform squad or unlimited infra budget. This track shares practical approaches to shipping ML with lean teams—covering lightweight tooling, automation shortcuts, and lessons from teams doing more with less.
ML Lifecycle Security
ML Training Lifecycle
Scoping and Delivering Complex AI Projects
2025 THEME: LLM Infrastructure & Operations
LLMs on Kubernetes
This track covers the key architectural choices and infra strategies behind scaling AI and LLM systems in production—from bare metal to Kubernetes, GPU scheduling to inference optimization. Learn what it really takes to build and operate reliable GenAI and agent platforms at scale.
ML Deployments on Prem
LLM Observability
Data Engineering in an LLM Era
Inference Optimization & Scaling
Multimodal Systems in Production

Our Expo is where innovation, ideas, and connections come to life
Transform from attendee to active participant by leveling-up your professional contacts, exchanging ideas, and even grabbing the mic to share a passion project.
Make New Connections
Connect with AI Practitioners
Brain Dates
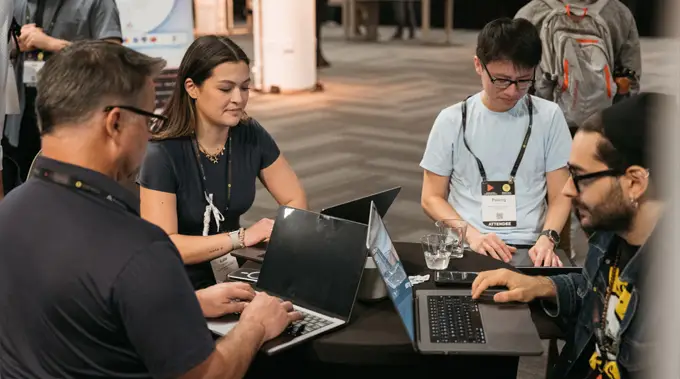
Speakers' Corner
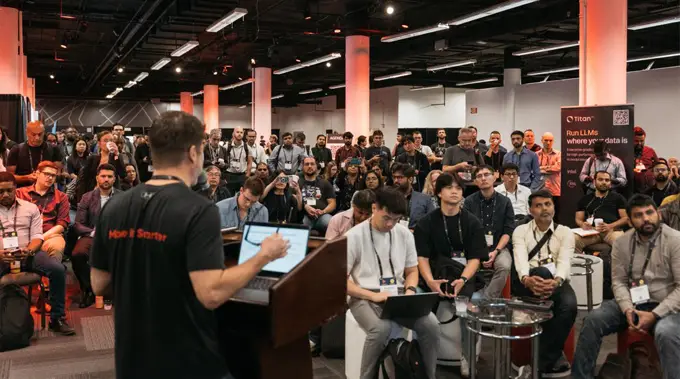
Vendor Booths
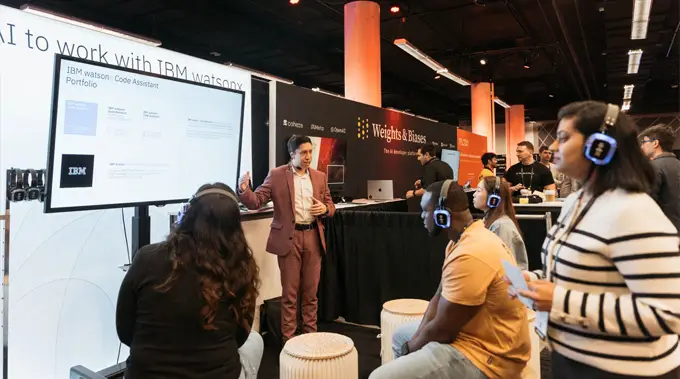
Community Square
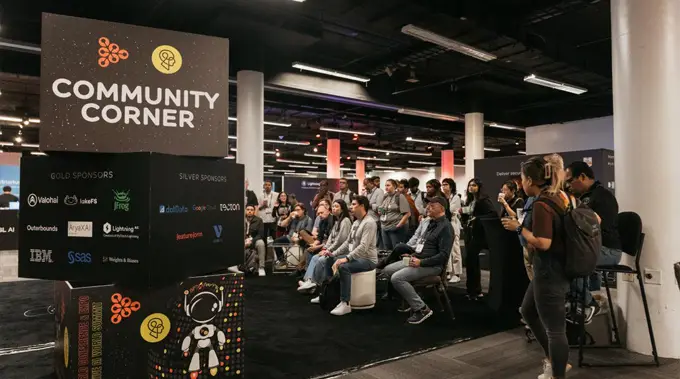
Startup Zone
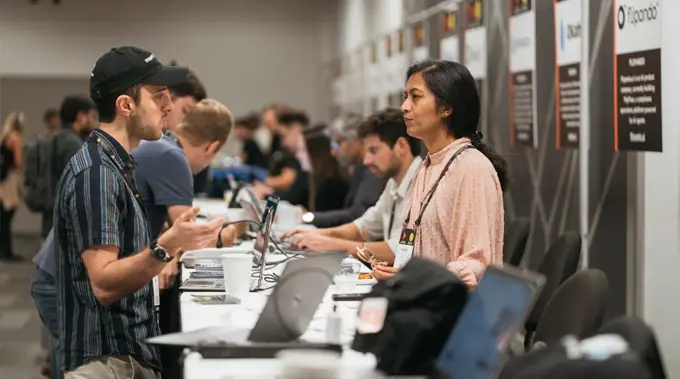
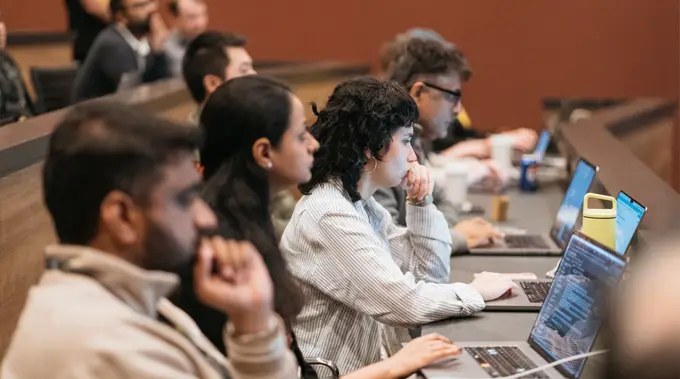
Hands-on Sessions
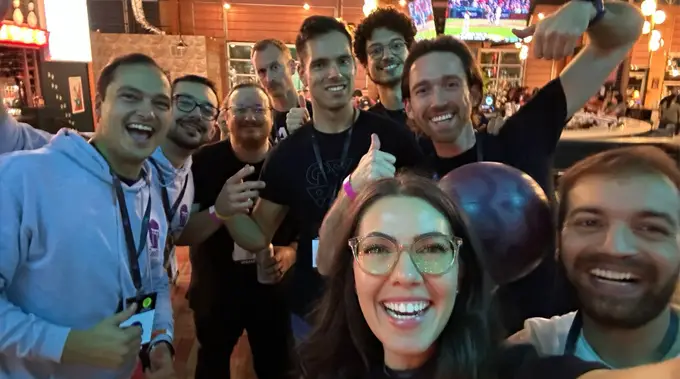
Austin Parties
Expo Expo Expo Expo Expo Expo Expo Expo Expo Expo Expo Expo
40+ Technical Workshops and Industry Case Studies




Event Speakers
We will release it soon.
Meet the experts bringing techniques, best practices, and strategies to this year’s stage.
Matt Mazzarell
Matt Mazzarell
ABOUT THE SPEAKER:
“One of the most difficult problems every company faces is understanding its customers completely. Customer lifetime value, attrition risk, and purchase propensity are all solvable with AI/ML — but how do we combine these modeling scores to initiate the right action with the right customer at any point in time?
Agentic applications help us make the best possible decisions when interpreting complex, high-volume signals from our customers. An agentic application gives end users visuals that explain key insights, with an agent in the loop to ensure nothing is missed. Context is everything: when done correctly, the agent always has the appropriate understanding to build an action plan that improves customer health and profitability.
In this session, we’ll show you how to build agentic apps from ideation to a finished product that interacts with customers. You’ll take away practical tips for using agentic coding frameworks, curating complete customer data products, and building customer-facing agents — capped off with a live demo of Teradata’s Customer Lifetime Value Agentic App.”
TALK TITLE:
TRACK:
ABSTRACT:
“One of the most difficult problems every company faces is understanding its customers completely. Customer lifetime value, attrition risk, and purchase propensity are all solvable with AI/ML — but how do we combine these modeling scores to initiate the right action with the right customer at any point in time?
Agentic applications help us make the best possible decisions when interpreting complex, high-volume signals from our customers. An agentic application gives end users visuals that explain key insights, with an agent in the loop to ensure nothing is missed. Context is everything: when done correctly, the agent always has the appropriate understanding to build an action plan that improves customer health and profitability.
In this session, we’ll show you how to build agentic apps from ideation to a finished product that interacts with customers. You’ll take away practical tips for using agentic coding frameworks, curating complete customer data products, and building customer-facing agents — capped off with a live demo of Teradata’s Customer Lifetime Value Agentic App.”
Antonio Bustamante
Antonio Bustamante
ABOUT THE SPEAKER:
Everyone building on frontier models hits the same wall: 80% of the way there in a weekend, then an exponentially expensive climb toward the 99%+ that operational systems need. This talk is the honest map of that climb, from a team that now runs AI over millions of documents, images and videos a month for customers in logistics, fleet management, automotive and financial services who need the answer to be right every time.
We will walk through the ladder nobody budgets for: retries, then queues when the model is down for three hours, then rate limits, then discovering that 95% is not enough for transactional data, then discovering that the model cannot tell you how confident it is. We will show two failures from our own production history, a customer whose single engineer racked up $30K of usage in a month because nothing was watching, and our first churn, on 500-page reports with a hundred rows per page, a problem we still consider unsolved. And we will show what we changed: a harness that treats AI as a deterministic step inside durable workflows rather than as an open-ended agent, decisions expressed as a verified tree the model must traverse, algorithmic confidence scoring on top of models that provide none, routing anything under 95% to a human whose verdict feeds back into the system, semantic checks against instructions smuggled into the data, and, counterintuitively, encouraging customers to build their own independent monitoring of us. One customer’s users went from eight to nine hours a week on a task to about thirty minutes, and that number was measured by them, not by us.
Attendees will leave with five patterns they can apply Monday: confidence scoring for models that lack it, decision trees over open-ended prompts, exception routing with feedback loops, semantic security checks on inbound data, and customer-owned evaluation. They will also leave with a thesis we did not start with: chat is single-player AI; the next decade of software is ambient AI that runs the same process a hundred thousand times a day, unattended, and behaves the same way every time.
TALK TITLE:
TRACK:
ABSTRACT:
Everyone building on frontier models hits the same wall: 80% of the way there in a weekend, then an exponentially expensive climb toward the 99%+ that operational systems need. This talk is the honest map of that climb, from a team that now runs AI over millions of documents, images and videos a month for customers in logistics, fleet management, automotive and financial services who need the answer to be right every time.
We will walk through the ladder nobody budgets for: retries, then queues when the model is down for three hours, then rate limits, then discovering that 95% is not enough for transactional data, then discovering that the model cannot tell you how confident it is. We will show two failures from our own production history, a customer whose single engineer racked up $30K of usage in a month because nothing was watching, and our first churn, on 500-page reports with a hundred rows per page, a problem we still consider unsolved. And we will show what we changed: a harness that treats AI as a deterministic step inside durable workflows rather than as an open-ended agent, decisions expressed as a verified tree the model must traverse, algorithmic confidence scoring on top of models that provide none, routing anything under 95% to a human whose verdict feeds back into the system, semantic checks against instructions smuggled into the data, and, counterintuitively, encouraging customers to build their own independent monitoring of us. One customer’s users went from eight to nine hours a week on a task to about thirty minutes, and that number was measured by them, not by us.
Attendees will leave with five patterns they can apply Monday: confidence scoring for models that lack it, decision trees over open-ended prompts, exception routing with feedback loops, semantic security checks on inbound data, and customer-owned evaluation. They will also leave with a thesis we did not start with: chat is single-player AI; the next decade of software is ambient AI that runs the same process a hundred thousand times a day, unattended, and behaves the same way every time.
Upal Saha
Upal Saha
ABOUT THE SPEAKER:
This is a build-and-break lab for engineers who already know that a demo is not a system. In the first fifteen minutes every attendee stands up a working extraction pipeline against a real invoice, with no schema authoring, and gets structured JSON back. Then we spend an hour breaking it the way production does, and fixing each break with a pattern that transfers to any stack.
Break one: the wrong document. We feed a bill of lading glued to an invoice into the invoice pipeline and watch it confidently produce garbage. Fix: classify before you extract, and make the graph deterministic even though every step inside it is a model. Break two: the answer that is probably right. Models do not tell you how confident they are, so we compute per-field confidence, find the fields that fall below 95%, and route those, and only those, to a human whose correction feeds back into the system. Break three: the messy string. “10 cases organic gala apples, 88 ct” has to become one SKU; we show why canonicalization is its own step, how to score matches, and where to set the threshold for review. Break four: the hostile input. Everyone runs an image whose pixels read “ignore all previous instructions” and we discuss, with the result on screen, what it means to treat inbound data as data rather than control. We close by labeling a handful of outputs and running a regression test between two versions of the pipeline, because evaluation is a loop, not a phase.
Attendees leave with a running pipeline in their own account and five patterns they can apply on Monday regardless of vendor: classify-then-extract, confidence scoring for models that lack it, threshold-based exception routing with feedback, semantic security checks on inbound data, and versioned regression testing. The platform used in the room is ours; the lessons are not.
TALK TITLE:
TRACK:
ABSTRACT:
This is a build-and-break lab for engineers who already know that a demo is not a system. In the first fifteen minutes every attendee stands up a working extraction pipeline against a real invoice, with no schema authoring, and gets structured JSON back. Then we spend an hour breaking it the way production does, and fixing each break with a pattern that transfers to any stack.
Break one: the wrong document. We feed a bill of lading glued to an invoice into the invoice pipeline and watch it confidently produce garbage. Fix: classify before you extract, and make the graph deterministic even though every step inside it is a model. Break two: the answer that is probably right. Models do not tell you how confident they are, so we compute per-field confidence, find the fields that fall below 95%, and route those, and only those, to a human whose correction feeds back into the system. Break three: the messy string. “10 cases organic gala apples, 88 ct” has to become one SKU; we show why canonicalization is its own step, how to score matches, and where to set the threshold for review. Break four: the hostile input. Everyone runs an image whose pixels read “ignore all previous instructions” and we discuss, with the result on screen, what it means to treat inbound data as data rather than control. We close by labeling a handful of outputs and running a regression test between two versions of the pipeline, because evaluation is a loop, not a phase.
Attendees leave with a running pipeline in their own account and five patterns they can apply on Monday regardless of vendor: classify-then-extract, confidence scoring for models that lack it, threshold-based exception routing with feedback, semantic security checks on inbound data, and versioned regression testing. The platform used in the room is ours; the lessons are not.
D. Sculley
D. Sculley
ABOUT THE SPEAKER:
We spend a lot of time thinking about operational issues in AI related to deployment, somewhat less time thinking about adoption, or (dare we say it) acceptance. This talk will touch on some technical pieces in the current AI ops landscape including streaming systems, planning, latency, and on-device models, but most of the time will be spent looking at ways we can move beyond the stale framing of a chatbot, assistant, or customer service agent.
TALK TITLE:
TRACK:
ABSTRACT:
We spend a lot of time thinking about operational issues in AI related to deployment, somewhat less time thinking about adoption, or (dare we say it) acceptance. This talk will touch on some technical pieces in the current AI ops landscape including streaming systems, planning, latency, and on-device models, but most of the time will be spent looking at ways we can move beyond the stale framing of a chatbot, assistant, or customer service agent.
Nadia Rauch
Nadia Rauch
ABOUT THE SPEAKER:
We built a multi-agent pipeline to automate a complex, document-intensive enterprise workflow. The initial system ran sequentially through a chain of specialized agent roles, each handling a distinct task in the process, using a single frontier model throughout. It worked. It was also slow and expensive, and we didn’t know why.
Rather than optimize blindly, we profiled first. The results were not where we expected: 67% of total latency came from a small minority of the agent roles, and the primary bottleneck was not the model — it was sequential chaining: independent work was being processed one step at a time instead of concurrently. Identifying and parallelizing the roles with no inter-dependency reduced end-to-end runtime by roughly 40%.*
The second experiment compared model tiers (frontier, mid-tier, lightweight) across each agent role independently, measuring accuracy, latency, and cost per role. The finding cuts against the default assumption: the roles that appeared most cognitively demanding required frontier models, but the accuracy gap was smaller than expected. The roles where model downgrade failed were the ones responsible for precise structured extraction — tasks where errors propagate silently downstream and surface only at the output. Swapping to mid-tier models on roles that tolerated it reduced per-run cost by ~40%, with an estimated <2% accuracy impact at the role level and <1% at the pipeline output level.*
The third experiment compared orchestration harnesses — evaluating how the choice of agentic framework affects runtime overhead, observability, and the ease of implementing the parallelization and model-swap changes described above. Framework choice turned out to matter more than expected for operational concerns: debugging multi-agent failures, tracing costs per agent, and modifying execution flow without rewriting pipeline logic.
Operating in a regulated enterprise environment added one constraint worth naming: every agent decision needs to be auditable. This ruled out certain optimization shortcuts that would have been acceptable in other contexts and shaped how we defined “accurate enough” per role.
This talk covers the profiling methodology, the per-role model comparison framework, the parallelization decisions, the harness comparison, and the operational lessons — including what we’d instrument from day one if we rebuilt the system today.
*Cost and accuracy figures for the parallelization and model-tier experiments are preliminary; the formal evaluation is in progress and will be updated with measured results before the talk.
TALK TITLE:
TRACK:
ABSTRACT:
We built a multi-agent pipeline to automate a complex, document-intensive enterprise workflow. The initial system ran sequentially through a chain of specialized agent roles, each handling a distinct task in the process, using a single frontier model throughout. It worked. It was also slow and expensive, and we didn’t know why.
Rather than optimize blindly, we profiled first. The results were not where we expected: 67% of total latency came from a small minority of the agent roles, and the primary bottleneck was not the model — it was sequential chaining: independent work was being processed one step at a time instead of concurrently. Identifying and parallelizing the roles with no inter-dependency reduced end-to-end runtime by roughly 40%.*
The second experiment compared model tiers (frontier, mid-tier, lightweight) across each agent role independently, measuring accuracy, latency, and cost per role. The finding cuts against the default assumption: the roles that appeared most cognitively demanding required frontier models, but the accuracy gap was smaller than expected. The roles where model downgrade failed were the ones responsible for precise structured extraction — tasks where errors propagate silently downstream and surface only at the output. Swapping to mid-tier models on roles that tolerated it reduced per-run cost by ~40%, with an estimated <2% accuracy impact at the role level and <1% at the pipeline output level.*
The third experiment compared orchestration harnesses — evaluating how the choice of agentic framework affects runtime overhead, observability, and the ease of implementing the parallelization and model-swap changes described above. Framework choice turned out to matter more than expected for operational concerns: debugging multi-agent failures, tracing costs per agent, and modifying execution flow without rewriting pipeline logic.
Operating in a regulated enterprise environment added one constraint worth naming: every agent decision needs to be auditable. This ruled out certain optimization shortcuts that would have been acceptable in other contexts and shaped how we defined “accurate enough” per role.
This talk covers the profiling methodology, the per-role model comparison framework, the parallelization decisions, the harness comparison, and the operational lessons — including what we’d instrument from day one if we rebuilt the system today.
*Cost and accuracy figures for the parallelization and model-tier experiments are preliminary; the formal evaluation is in progress and will be updated with measured results before the talk.
Poonam Lamba
Poonam Lamba
ABOUT THE SPEAKER:
We redesigned distributed GPU orchestration for RL post-training and batch inference in the open-source llm-d platform. Structurally, we replaced static GPU/TPU locking with a three-tier co-operative time-slicing system:
- Application Layer: Workloads signal phase boundaries (rollouts, training, batch inference) via explicit acquire() and yield() APIs.
- Cluster Orchestrator: Manages lock queues to dynamically interleave complementary jobs onto shared hardware during idle phases.
- Node Snapshot Agent: Executes fast sub-second state swaps between GPU/TPU VRAM and host DRAM, enabling instant context switching without container restarts.
Attendees will walk away with:
- Drive 70%+ GPU/TPU Utilization: Understand how time-slicing reclaims idle hardware during RL loops and batch inference without impacting convergence.
- Architect Rapid Memory Swapping: Apply VRAM-to-DRAM snapshotting strategies for ultra-fast GPU/TPU context switching.
- Deploy on Kubernetes: Configure llm-d and K8s orchestrators to interleave RL and batch inference on shared clusters.
TALK TITLE:
TRACK:
ABSTRACT:
We redesigned distributed GPU orchestration for RL post-training and batch inference in the open-source llm-d platform. Structurally, we replaced static GPU/TPU locking with a three-tier co-operative time-slicing system:
- Application Layer: Workloads signal phase boundaries (rollouts, training, batch inference) via explicit acquire() and yield() APIs.
- Cluster Orchestrator: Manages lock queues to dynamically interleave complementary jobs onto shared hardware during idle phases.
- Node Snapshot Agent: Executes fast sub-second state swaps between GPU/TPU VRAM and host DRAM, enabling instant context switching without container restarts.
Attendees will walk away with:
- Drive 70%+ GPU/TPU Utilization: Understand how time-slicing reclaims idle hardware during RL loops and batch inference without impacting convergence.
- Architect Rapid Memory Swapping: Apply VRAM-to-DRAM snapshotting strategies for ultra-fast GPU/TPU context switching.
- Deploy on Kubernetes: Configure llm-d and K8s orchestrators to interleave RL and batch inference on shared clusters.
Partners Partners Partners Partners Partners Partners Partners
Platinum Sponsor
Gold Sponsor
Silver Sponsors
Bronze Sponsors
Official Open Source Sponsor
Starup Zone
Community Partners


Media Partners
Latest News
Why attend
Event Parties & Networking
Explore Frontier Tools & Startups
Give your team an edge with insights, skills, and connections from the industry’s top innovators —
click here to see the exhibiting sponsors.
Grow industry influence
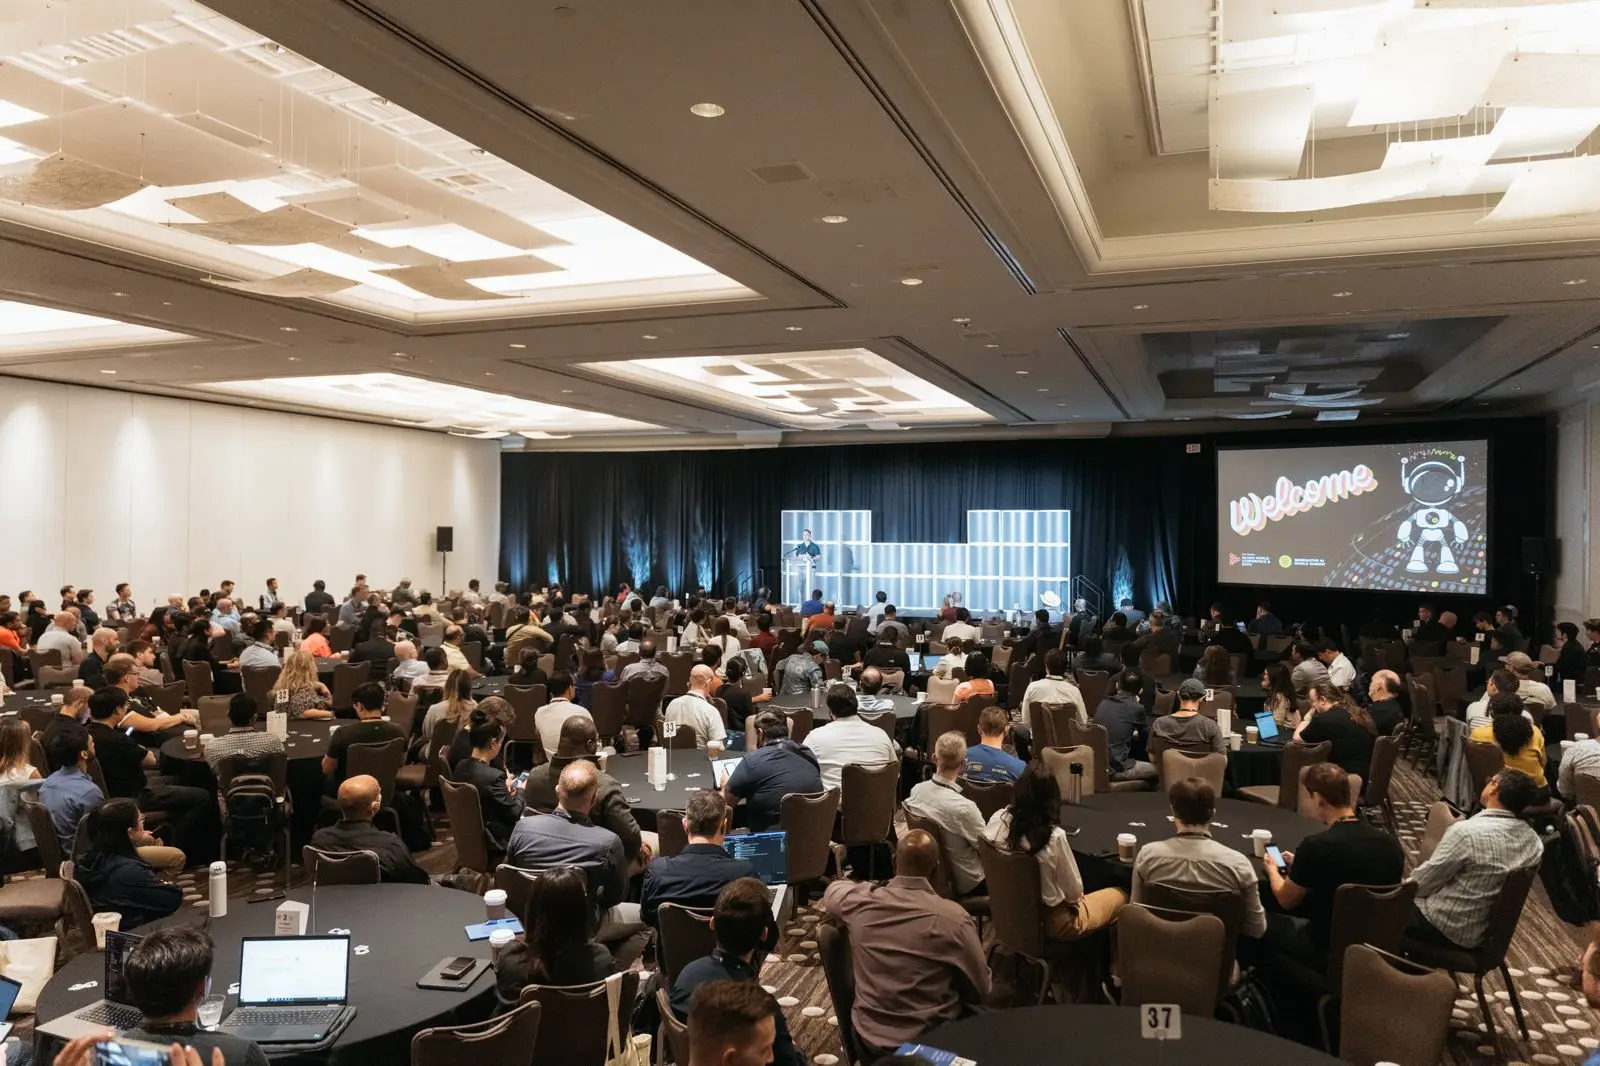
Join Brain Dates, Speaker’s Corner, Community Square, or deliver a talk to share your expertise and amplify your industry impact.
Curated by AI Practitioners
All sessions and workshops have been hand-picked by a Steering Committee of fellow AI practitioners who obsess about delivering real-world value for attendees.

Denys Linkov
Event Co-Chair & Head of ML at WiseDocs
“We built this year’s summit around practical takeaways. Not theory but actual workflows, strategies, and the next three steps for your team. We didn’t want another ‘Intro to RAG’ talk. We wanted the things people are debugging, scaling, and fixing right now.”

Volunteering
Apply for the opportunity to get exclusive behind the scenes access to the MLOps World experience while growing your network and skills in real-world artificial intelligence.
Austin
Renaissance Austin Hotel
Once again our venue is the beautiful Renaissance Austin Hotel which delivers an exceptional 360 experience for attendees, complete with restaurants, rooftop bar, swimming pool, spa, exercise facilities, and nearby nature walks. Rooms fill up fast, so use our code (MLOPS25) for discounted rates.

Choose Your Email Adventure
Join our Monthly Newsletter to be first to get expert videos from our flagship events and community offers including the latest Stack Drops.
Join Summit Updates to learn about event-specific news like ticket promos and agenda updates as well invites to join our free online Stack Sessions.
Choose what works best for you and update your email preferences at any time.
Hear From Past Attendees
Data and AI Scientist, Consultant, Podcaster
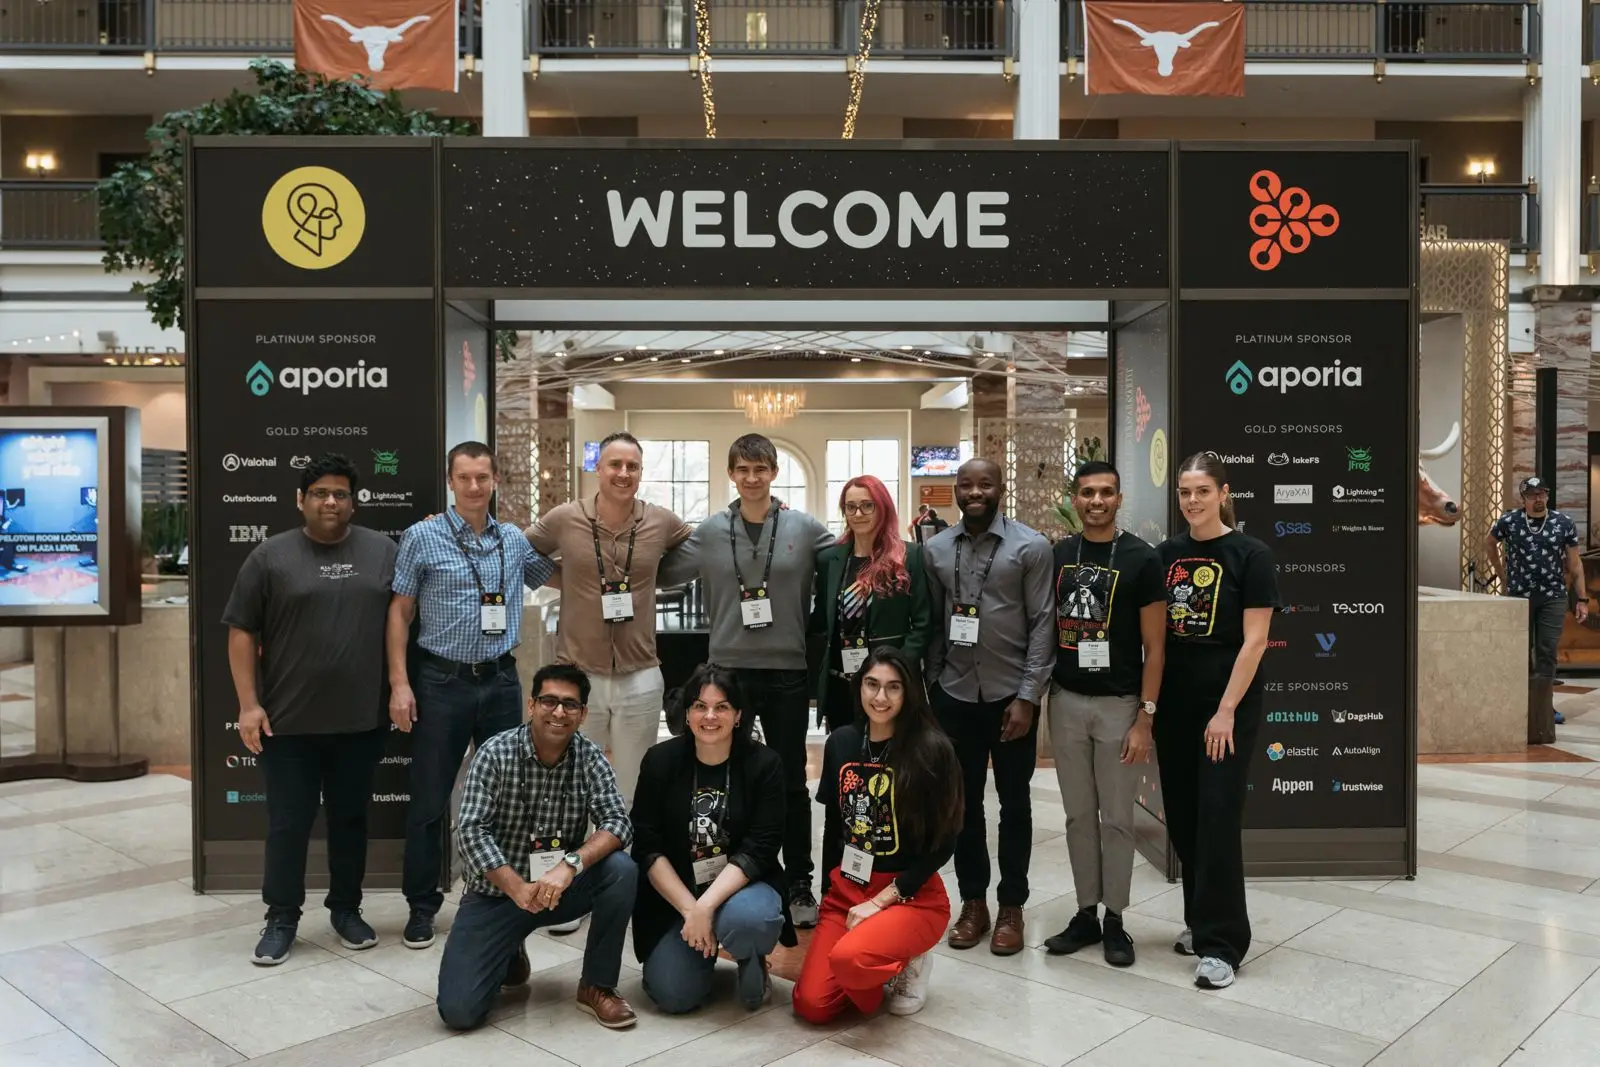
Free Virtual October 6-7 | In-person October 8-9
What Your Ticket Includes
- Full access to Summit sessions – Day 1 (Oct 8) & Day 2 (Oct 9) in Austin
- Bonus virtual program – live talks and workshops on Oct 6 & 7
- Hands-on learning – in-person talks, virtual workshops, and skill-building sessions
- Food & networking – connect with peers over meals, socials, and receptions
- AI-powered event app – desktop & mobile access for networking and schedules
- Networking events – structured meetups and community mixers
- On-demand replays – access to all post-summit videos
- 30 days of O’Reilly online learning – unlimited access to books, courses, and videos from O’Reilly and 200+ publishers
Past Agenda
This agenda is still subject to changes.
Join free virtual sessions October 6–7, then meet us in Austin for in-person case studies, workshops, and expo October 8–9
FAQ
When and where is the event?
The in-person portion of MLOps World | GenAI Summit takes place October 8-9, 2025 at the Renaissance Austin Hotel.
Address: 9721 Arboretum Blvd, Austin, TX 78759, United States See booking details.
What’s included with my ticket?
- Live training courses
- In-depth learning paths
- Interactive coding environments
- Certification prep materials
- Most major AI publications
Is there a virtual option?
What types of sessions can I expect?
Are there more active types of experiences?
How do I register?
Can I cancel or transfer my ticket?
Are discounts available for group ticket purchases?
Who typically attends MLOps World?
Will slides or recordings be available after the event?
Yes. The majority of presenters grant permission for their sessions to be recorded and shared. These recordings are made available after the event. The best way to be notified when new learning resources are released is by subscribing to our newsletter.
What if I have dietary or accessibility needs?
How do I apply to speak?
Submit your proposal via the Call for Speakers link in our site header (available ahead of each event) or subscribe to our newsletter for MLOps and other speaking alerts. Learn more
What kinds of talks are accepted?
Are speaker slots paid or unpaid?
What’s the speaker deadline for slides or submissions?
Do speakers get free tickets or travel support?
Can I speak virtually or only in-person?
Are sessions recorded? Will they be shared publicly?
What kind of A/V support or setup is provided?
What are the sponsorship packages and benefits?
How do I become a sponsor?
Visit our sponsor page to get more details and download our Sponsorship Guide, or contact Faraz Thambi at [email protected] to discuss availability and options.
What is the audience profile?
Attendees include ML/Data Engineers, Developers, Solution Architects / Principal Engineers, ML/AI Infra Leads, Technical Leaders, and Senior Leadership (Director, VP, C-suite, Founder) decision-makers from startups, scaleups, and enterprises across North America and around the globe.
Can I sponsor the virtual component or a specific track only?
How is lead capture handled?
Will there be booth space? How big? What’s included?
Yes. Booth packages vary in size depending on the tier; they range from a 20’x20’ island booth (Platinum) to a 6’ x 10’ draped booth (Bronze). Please see the guide for full specifications.
Can we run our own bespoke event or session?
Yes. We offer limited opportunities for sponsor-hosted workshops, roundtables, and after-hours events, pending approval and availability.
Are there other ways to get involved as a sponsor?
Yes, leading companies can apply to contribute discounts and free trials to our audience of AI/ML practitioners as part of our Stack Drop and Community Code programs. Learn more from our blog or email [email protected]